

Cloud & DevOps: from a local app to a reliable service Lesson 24 of 24
Observability, backups, and a recovery drill
Define service indicators, create a verifiable backup, restore data, and write a blameless final report.
This text was translated with AI.
This lesson starts from zero. An unfamiliar word is not treated as your deficiency: we first build an image, then give it a precise meaning, and only then use it.
Where we are
Flight review. The previous lesson used the support Deployment wants Pods → Service finds ready Pods → probes steer traffic → rollout changes gradually. Without looking, name its four links, then compare with the written signal.
Lesson outcome
Define service indicators, create a verifiable backup, restore data, and write a blameless final report. Do not move on until you can explain what every command verifies and which failure it can reveal.
Begin with a familiar image
When a building loses water, restarting the pump is insufficient. Determine who was affected, stop the leak, restore supply, test water quality, and reduce recurrence. A service incident follows the same path; blame obstructs fact gathering.
An analogy starts reasoning but does not replace the technology. We make every word precise below.
The lesson’s support signal
detect → limit impact → restore service/data → verify → learn → owner+date
Read the chain left to right. It answers not “which command should I memorise?” but “why does each step follow the previous one?”
New words in plain language
- Observability — The ability to ask new questions about a system through its outputs.
- Metric / log / trace — A metric shows a number over time, a log records an event, and a trace follows one request.
- Incident — An unplanned event that harms or threatens a service.
- Restore drill — A safe rehearsal restoring a backup into an isolated location.
Take it apart without rushing
Logs explain individual events, metrics show numbers changing over time, and traces connect a request path. A backup is useful only after a restore. An incident ends after service is restored, evidence is preserved, and follow-up work reduces recurrence, not merely after a restart.
Do not memorise this wording. Find its cause-and-effect link and attach it to the support signal above.
Predict the result first
Before running anything, write what should change, what should remain unchanged, and which output would support your prediction. A wrong prediction is useful when you can explain the difference after observing it.
Experiment in small steps
Run the commands from the course/cloud-devops-lab root. The commands target a learning environment. Read a command in full and check the current directory before it changes a server or data. Run one meaningful group at a time. Stop after each group and compare evidence with your prediction.
curl -fsS http://127.0.0.1:8080/metrics 2>/dev/null || true
mkdir -p backups
./scripts/backup.sh 2>/dev/null || true
printf 'A real drill restores into an isolated volume first.\n'
printf 'Record: detection, impact, timeline, recovery, evidence, follow-up owner and date.\n'
What this experiment actually does
First capture a metric and preserve facts. The backup receives a UTC timestamp and checksum. Restoration occurs in an isolated place where content is compared. The report records impact, timeline, resolution, and an owner for follow-up.
What you should observe
- The metric is connected to a user outcome.
- The command exits with a predictable status.
- The result can be repeated in a clean environment.
Rebuild the whole from the support map
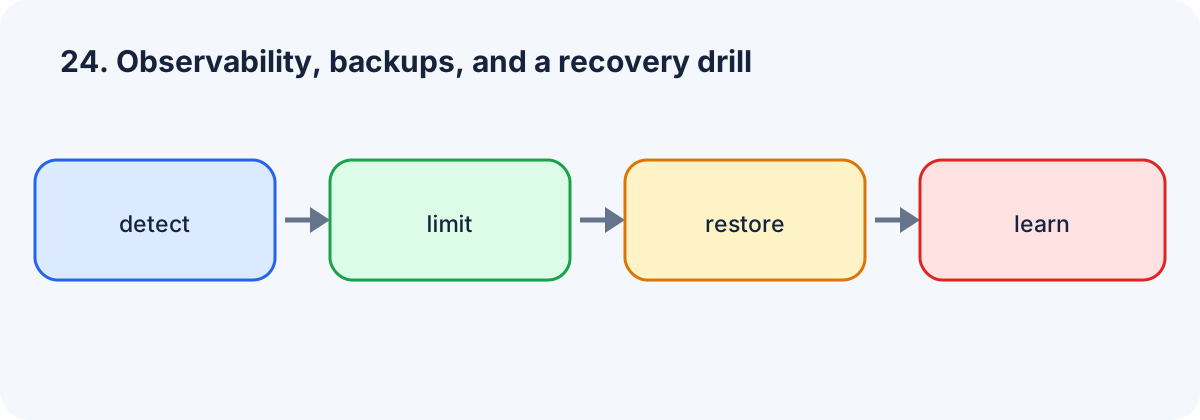
Follow the four blocks with a finger or pencil and tell the entire lesson as one connected explanation.
Recall without a prompt
- Hide the map and draw its four blocks from memory.
- Explain every transition using the word “because”.
- Define one new term without repeating the text verbatim.
- Name one signal that proves the result.
Find and correct the mistake
Mistake: “The incident ends when the service returns 200.” Correction: verify user outcomes and data, preserve evidence, and assign work to reduce recurrence.
Exercise
Now rebuild the same meaning yourself. You may use the support map; the goal is a repeatable result rather than a memory exam.
Required. Write a POSIX sh directory backup script with a UTC-stamped archive, adjacent SHA-256, archive verification, and no source deletion. Then list commands for a test restore into a new directory. Submit only POSIX sh commands or a script, with no real keys or tokens.
Completion criteria
- You understand every line you run.
- A repeat gives the expected result or a safely explained difference.
- Output contains no real keys, tokens, or passwords.
- You can point to evidence that proves success.
If a check fails, record expected and actual results, revisit the one broken support link, and retry. An error does not remove your right to continue learning.
Optional. Write down one possible failure and the signal that would reveal it.
Open perspective
This is the final lesson. Reconstruct the full course path: change, verification, release, observation, and proven recovery.
If you have found a mistake or a typo in this article, tell us about it
Comments (0)
Log in to leave a comment →
No comments yet. Be the first.