

Informatics: build your own digital assistant Lesson 64 of 72
Features, labels, and an honest dataset
We want the assistant to sort study tasks.
Where we are on the map
Lesson 64 of 72. AI and project release block (63–72). The assistant keeps its earlier reminder rules and local database; the new feature only suggests a task category and can abstain.
Situation and question
We want the assistant to sort study tasks. If every maths example only contains the word “maths”, the model may memorise that word and fail on “fractions”. Check where the data came from and whether they vary.
New words without gaps
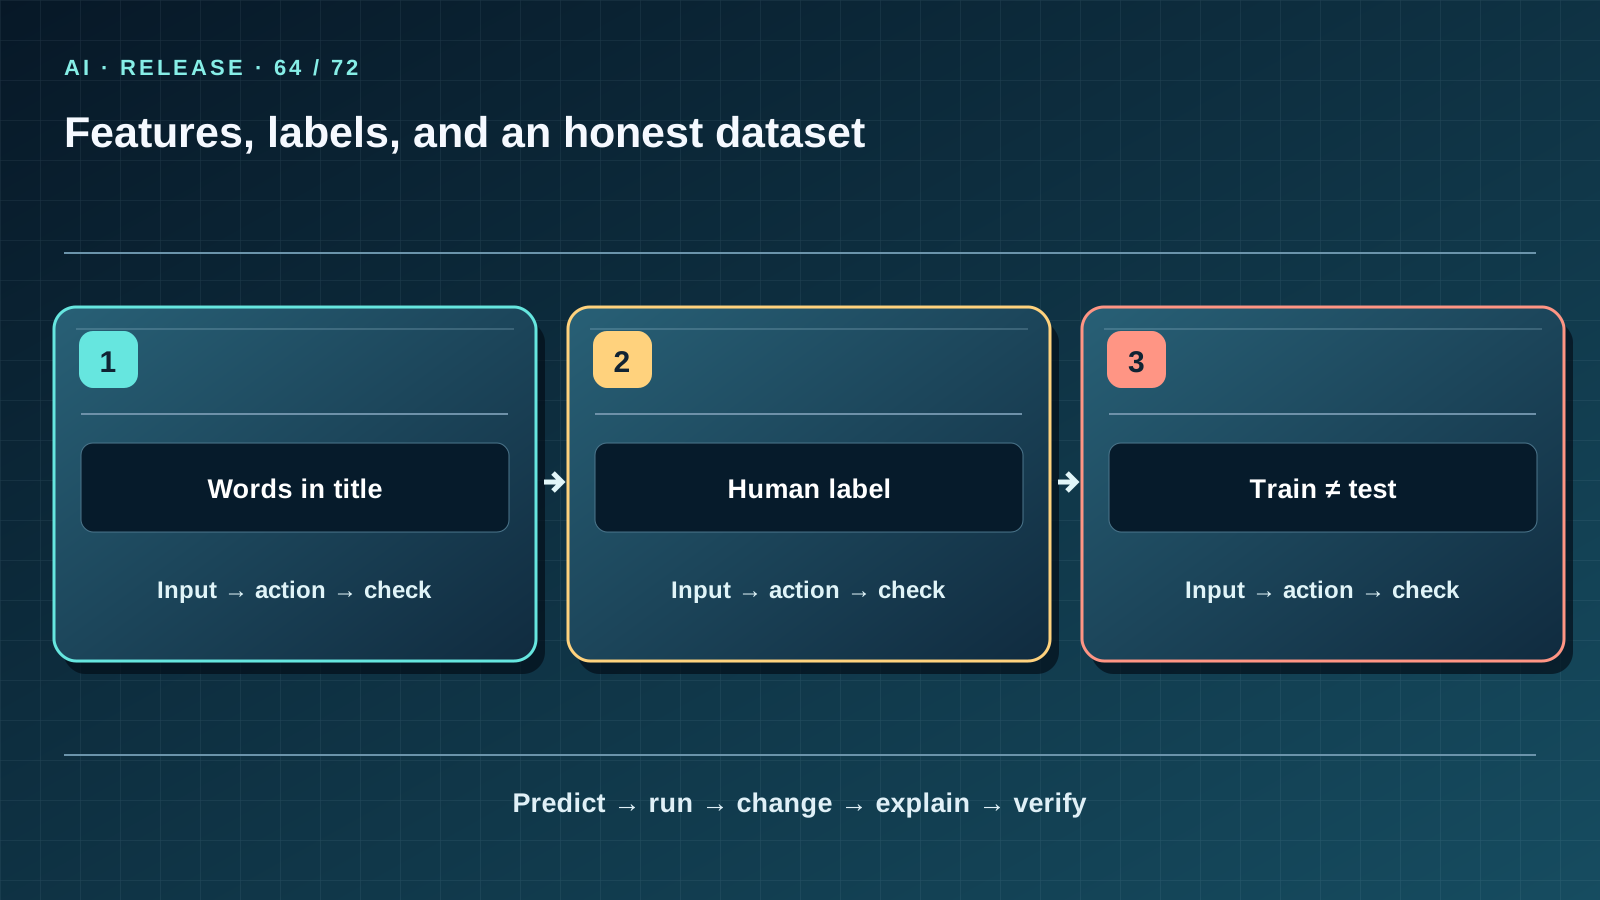
A feature is a measurable input property: the words in a title. A label is the category a person assigns to an example. A dataset is a table of examples with clear collection rules. A train/test split leaves some rows for independent checking; test rows must not train the model. Data leakage occurs if an answer from the test set enters training ahead of time.
The lesson’s support signal
Read the three cells left to right, then cover the third. State the input and action in each cell; predict how the path ends and which observable fact checks it. Compare the drawing with a project file or worked example. If a number on the map cannot be derived from the data, correct the map rather than changing data for a pretty picture.
Work through it step by step
Open labelled_tasks.csv: it has 16 fictional rows, 12 train and 4 test, with no names, marks or private messages. In Кітап оқу,reading,train, identify input, label and split. Confirm Кітап туралы жазу is not among training rows. Compare Kazakh and English words: this model does not translate automatically and needs examples for each language.
Predict and check
Write the expected output before running code. Execute it in step-06 or step-07, compare every character and explain each line. Then change one safe fictional input and repeat “predict — run — change — explain — verify.” Do not turn an observation on a tiny dataset into a promise about real people.
from classifier import read_examples
rows = read_examples("labelled_tasks.csv")
print(sum(r["split"] == "train" for r in rows), sum(r["split"] == "test" for r in rows))
Expected output
12 4
Catch the error
A label may be wrong or disputed. Duplicating a task in both train and test can inflate the score. Four held-out rows cannot justify a claim about all learners.
Project change
Release 2.1 preserves the DB, report, reminders and backup. labelled_tasks.csv contains fictional examples only. classifier.py suggests math, reading or review but writes no decision to the database. Check each model output against held-out examples and let a person reconsider it.
Task and evidence
Add two fictional titles on paper, one clear and one ambiguous. Assign labels, explain why, and choose two examples to reserve only for evaluation.
Transfer to a new setting
A model sorts library books by title. What happens to a book written in a language absent from training?
Return after 1, 7, and 30 days
After 1 day redraw the map from memory and name one boundary of the idea. After 7 days explain it to a friend without reading the lesson and answer 7 of 10 block questions; analyse mistakes with concrete inputs. After 30 days open a fresh project copy, reproduce the check and transfer the idea to a new case. Keep a record of input, expected output and actual output.
Primary reference to check
Next lesson
If you have found a mistake or a typo in this article, tell us about it
Comments (0)
Log in to leave a comment →
No comments yet. Be the first.